

I run my businesses with 38 AI agents. They watch 20 directory websites, manage SEO across 10 tenants, track revenue, probe for errors, and report back to me on Telegram every 15 minutes.
On August 23rd, my system told me everything was fine. “No critical failures.” Green across the board.
Then I never heard from it again!
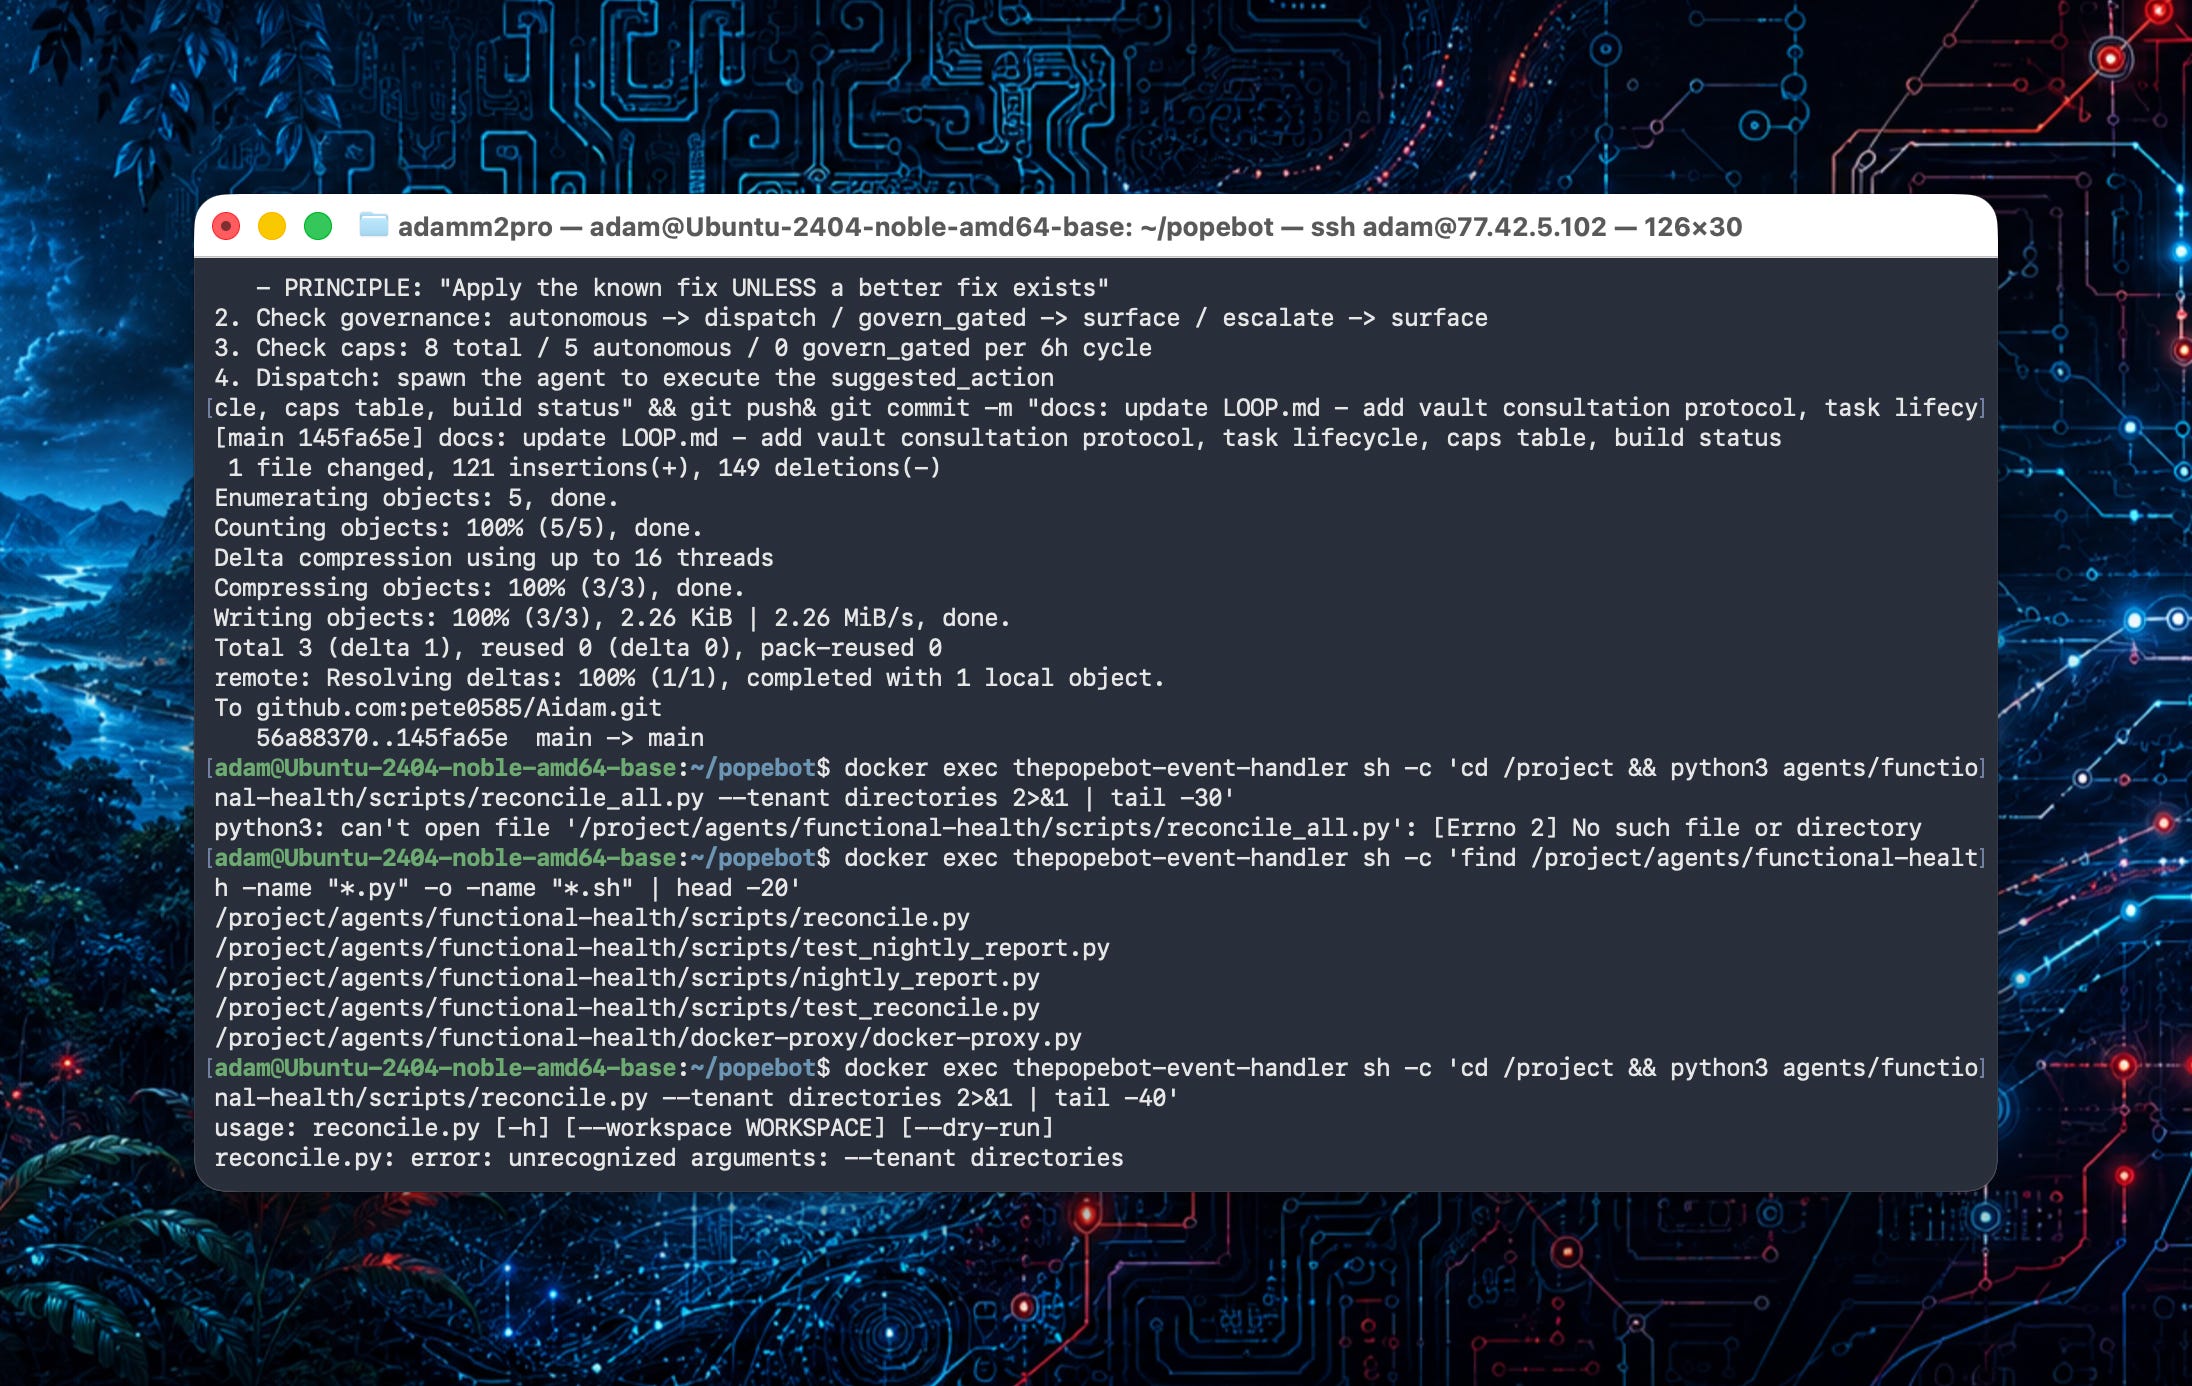
So I dug in, and what i discovered over the last 8 days is what im going to show you next.
Twenty-six of those agents had never run.
26!
Not once. Not a single job executed.
The system wasn’t reporting their failure. It was ignoring their absence. “No critical failures” was technically true because it wasn’t checking for the agents that didn’t exist yet.
That’s the AI equivalent of a security guard who says “nothing happened tonight” because he was asleep the whole shift. Nothing happened that he SAW. But he wasn’t looking.
And here’s the kicker: I’m the guy building “managed AI operations” as a service. I literally sell this. My own system was doing the exact thing it exists to prevent.
You Probably Have This Problem Too
If you’re running AI agents on your business - and at this point, a lot of you are - you have this problem. Maybe not 26 dead agents. But you’ve got agents that report success when the output is empty. Dashboards that say “healthy” when nothing’s actually being checked. A Zapier workflow that silently stopped running three weeks ago and nobody noticed until a customer complained.
AI agents lie in ways servers don’t. A server is down or it’s up. An AI agent can report success while doing nothing. It can claim a task is complete when the output is empty. It can say “no critical failures” while half your fleet doesn’t exist.
The question isn’t whether this is happening to you. It’s whether you know it’s happening.
The Receipts
I didn’t fix this with a patch. I fixed it with a principle: receipts, not claims.
Every agent now writes a last-run.json file when it executes. The receipt has a timestamp, a result (ok / no_work / failed / error), and whatever output the agent actually produced. No receipt means the agent didn’t run. No “nominal.” No “healthy.” Either you have a receipt, or you don’t.
I converted 26 dead agents into Python command crons wrapped in a receipt-writing layer. Each one executes its job, writes a receipt with the actual result, commits it to git, and pushes to GitHub. If the push fails, the receipt still exists locally. If the job fails, the receipt says “failed” - not “completed successfully.”
The system can no longer lie because the receipt IS the proof, and the proof is in version control.
After the fix: 21 agents reporting result=ok. 4 agents gated by design (they need human approval before acting). 2 agents need credentials I haven’t configured yet. 2 agents were never broken - they correctly reported zero results because there was nothing to do.
Zero agents lying. Every receipt verifiable. Every claim backed by a file you can read.
The Loop
So receipts solved the honesty problem. But honesty isn’t enough. A system that tells the truth about being broken is just a well-documented disaster. I needed it to fix itself.
I built a loop. Not a metaphor - an actual closed loop that runs every 6 hours:
Sensor - scans for gaps. Failed receipts, degraded tenants, agents that haven’t run, sites returning errors. Anything that should be working and isn’t.
Triage - writes each gap as a task with a suggested fix and a governance level. Autonomous, human-gated, or escalate.
Dispatch - sends agents to fix the gaps. Hard caps: 8 total fixes per 6-hour cycle, 5 autonomous. A kill switch that halts everything instantly if it goes sideways.
Measure - re-checks the gap after the fix. If it’s better, mark done. If it’s worse, rollback. If it’s unchanged, try next cycle again.
Learn - writes what happened back to a knowledge base. What broke, why, and how it was fixed. Next time the same gap appears, the system reads the history first.
That last step is the one nobody’s talking about. Most AI monitoring systems detect, alert, and maybe fix. They don’t learn. Every cycle is a fresh start. My system reads its own history before acting. “Last time this agent failed, it was because the API key expired. Check the key first.” That’s the difference between a monitoring system and a self-improving one.
Missions stall on the smallest things at the worst moments. The knowledge base makes sure you only stall on each thing once.
What This Looks Like for Someone Else
Here’s where it gets interesting. Let’s say I take on a client - a holistic dentistry practice with 12 locations across three states. They need appointment scheduling automation, review monitoring across 12 Google Business profiles, insurance verification workflows, patient follow-up sequences, and a directory presence on the sites their patients actually search.
That’s a 6-week build for most consultants. First week: figure out the APIs. Second week: break things. Third week: fix what broke. Fourth week: discover something else is broken. You know how it goes.
But my system has already built 20 directory sites. It’s already learned every way a directory breaks. It’s already documented why NODE_ENV=production silently breaks npm installs, why Playwright blocks file:// protocol, why Resend’s API rejects non-browser User-Agents. Each of those cost me hours. Each is now a 10-second read for the system.
When I onboard the dental client, the system doesn’t start from zero. It reads everything it learned building my businesses and assembles it from proven patterns. Their first week isn’t my first week. It’s my 20th.
That’s the whole point. Not the monitoring. Not the receipts. The compounding knowledge that makes every next build faster than the last one. The first client took me weeks. The tenth takes days. The fiftieth takes hours. Not because I got faster - because the system got smarter.
Why I’m Publishing This
I sell Managed AI Operations through my company, Studio Zero. The pitch is simple: I run 20+ AI agents on my own revenue businesses and show my work. Not “trust me, it works.” Watch me.
This is me watching. The terminal output, the git commits, the receipts, the failures. All of it. I’m publishing the embarrassing part - the system that lied - because that’s the proof the rest isn’t marketing.
The category is forming right now. Companies are naming it, describing it, building pitch decks. But nobody’s demonstrating it on their own business with their own receipts in version control. That’s the gap. That’s the whole-ass moat.
Watch me, not trust me.
Studio Zero, powered by AIdam. If you want to see the receipts, they’re in version control. If you want to talk about running this for your business, book a call.